A/B Testing
Principal Stratification and Mediation
This post explores principal stratification and mediation analysis as tools for understanding causal effects, decomposing them into direct and indirect components. It covers scenarios like non-compliance, missing outcomes, and surrogate indices, highlighting the importance of assumptions such as no direct effects and no Defiers. Practical methods, including multiple imputation, regression, and matching, are discussed for estimating effects even when key quantities are unobserved. Real-world examples, like marketing lift studies and product funnels, illustrate the relevance of these techniques for addressing complex causal questions.
Modes of Inference in Randomized Experiments
Randomization provides the “reasoned basis for inference” in an experiment. Yet some approaches to analyzing experiments ignore the special structure of randomization. Simple, familiar approaches like regression models sometimes give wrong answers when applied to experiments. Approaches exploiting randomization deliver more reliable inferences than methods neglecting it. Randomization inference should be the first method we reach for when analyzing experiments.
Tests with One-Sided Noncompliance
Introduction Tech companies spoil data scientists. It’s so easy for us to A/B test everything. We can alter many aspects of the product from a configuration UI. We have the sample size to get a good read in as little as a few days. We have the data infrastructure to analyze and report results quickly.
The Winner's Curse: Why it Happens and What to Do About It
When running an A/B test with many variants, say, more than 5, we often run into a phenomenon known as the Winner’s Curse, where the winning variant performs worse when we adopt it universally than it had during the test itself. In this post, we discuss why this phenomenon occurs and what to do about it.
Robust Portfolio Optimization in Generalized Linear Models
Often we run an A/B test in order to inform some decision. But every A/B test involves uncertainty, no matter the sample size. This uncertainty poses a risk to our decision, which can be hedged by a process analogous to diversifying an investment portfolio. Finding a robust-optimal portfolio is both practical and fast.
Bayesian A/B Testing Considered Harmful
In science we study physically meaningful quantities that have some kind of objective reality, and that means that multiple people should draw substantively equivalent conclusions. But in some situations, this principle is at odds with the Bayesian Coherency Principle, and so we have to choose between internal consistency, or consistency with external reality.
Testing with Many Variants
This is a long drive for someone with nothing to think about.
Robust Power Assessment
An important part of planning any statistical experiment is power analysis. In this post I will focus on power analysis for linear regression models, but I am hopeful much of this can be applied to Generalized Linear Models and hence to the sorts of A/B tests I normally run.
Scheffe's Method for Multiple Comparisons
I’ve written previously about using the Bonferroni correction for the multiple comparisons problem. While it is without a doubt the simplest way to correct for multiple comparisons, it is not the only way. In this post, I discuss Scheffé’s method for constructing simultaneous confidence intervals on arbitrarily many functions of the model parameters.
Multiple Comparisons
The simplest kind of A/B test compares two options, using a single KPI to decide which option is best. The more general theory of statistical experiment design easily handles more options and more metrics, provided we know how to incorporate the multiple comparisons involved. To see why this is important, read on!
Violations of the Stable Unit Treatment Value Assumption
We have previously mentioned the Stable Unit Treatment Value Assumption, or SUTVA, a complicated-sounding term that is one of the most important assumptions underlying A/B testing (and Causal Inference in general). In this post, we talk a little more about it and why it is so important.
Contingency Tables Part IV: The Score Test
The score test can be used to calculate p-values and confidence intervals for A/B tests. The score test considers the slope of the likelihood function at the parameter value associated with the null hypothesis.
Sprinkle some Maximum Likelihood Estimation on that Contingency Table!
Maximum Likelihood Estimation provides consistent estimators, and can be efficiently computed under many null hypotheses of practical interest.
Contingency Tables Part II: The Binomial Distribution
In our last post, we introduced the potential outcomes framework as the foundational framework for causal inference. In the potential outcomes framework, each unit (e.g. each person) is represented by a pair of outcomes, corresponding to the result of the experience provided to them (treatment or control, A or B, etc.)
Contingency Tables Part I: The Potential Outcomes Framework
“Why can’t I take the results of an A/B test at face value? Who are you, the statistics mafia? I don’t need a PhD in statistics to know that one number is greater than another.” If this sounds familiar, it is helpful to remember that we do an A/B test to learn about different potential outcomes. Comparing potential outcomes is essential for smart decision making, and this framework is the cornerstone of causal inference.
Unshackle Yourself from Statistical Significance
Don’t be a prisoner to statistical significance. A/B testing should serve the business, not the other way around!
A/B Testing
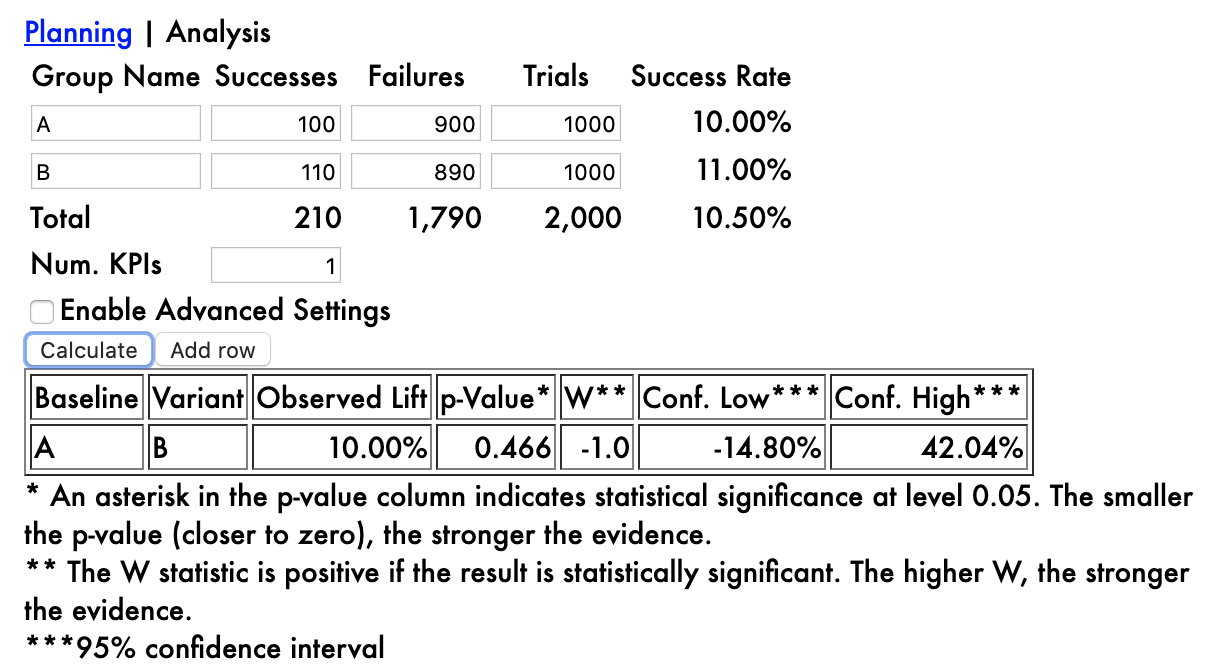
Calculators for planning and analyzing A/B tests
A/B Testing Best Practices
When I started this blog, my primary objective was less about teaching others A/B testing and more about clarifying my own thoughts on A/B testing. I had been running A/B tests for about a year, and I was starting to feel uncomfortable with some of the standard methodologies. It’s pretty common to use Student’s t-test to analyze A/B tests for example. One of the assumptions underlying that test is that the distributions are Gaussian. “What about A/B testing is Gaussian?”, I wondered. I knew there was a big difference between one-sided and two-sided tests, but I didn’t feel confident in my ability to choose the right one. And the multiple comparisons problem seemed to rear its ugly head at every turn: what was the best way to handle this?
Optimal Experiment Design
We can plan sample sizes to control the width of confidence intervals.
Confidence Intervals
Statistical analysis is not complete without an estimate of residual uncertainty.
Statistical Power
Power considerations drive the sample sizes needed for a successful experiment.
Counterfactuals and Causal Reasoning
What does ‘Why?’ mean anyway?
Fisher's Exact Test
Simulation-based inference sits on a rigorous foundation.
A/B Testing, Part 2: Statistical Significance
Results can’t always be taken at face value.
A/B Testing, Part 1: Random Segmentation
Random segmentation is the gold standard of Causal Inference.